
Yesterday's signals, distilled, A look back at October 17, 2026.
Compute is getting financed like infrastructure.
Not “capex on a balance sheet” infrastructure. Credit committees, yield targets, and underwriting infrastructure.
At the same time, the model layer keeps pushing in two directions that look contradictory but aren’t: cheaper, leaner models on one end; bigger, more capital-intensive training and inference commitments on the other.
And the risk perimeter is widening in a way that will hit operators before it hits policy teams. Insurers are starting to treat AI incidents as a claims category that can outrun existing limits. Security teams are dealing with industrialized phishing supply chains that can throw a billion messages at the market.
Underneath all of it is a single operational question: do you know which parts of your AI roadmap are constrained by capability, and which are constrained by capital, coverage, and custody.
CAPITAL FLOWS / FRONTIER COMPUTE
Frontier compute is being priced by the cost of capital, not the cost of chips
Anthropic–Blackstone TPU financing talks surface a $60B debt package
Sources told the Financial Times that Anthropic is offering Blackstone a 10%+ yield to help finance a $60B debt package to buy Google TPUs, with Blackstone potentially investing $9B in the debt, per Financial Times.
This is not a “funding round” story. It’s a balance-sheet architecture story, frontier labs and their partners are experimenting with infrastructure-style financing to lock in compute supply at scale.
The Bet: Long-duration compute access is worth paying infrastructure-grade yields for, because the alternative is being supply-constrained at the moment demand inflects.
So What? If double-digit yields become normal for frontier compute financing, model pricing pressure doesn’t just come from GPU/TPU supply. It comes from interest expense and refinancing risk. That flows downstream: enterprise buyers should expect more variability in long-term pricing, more appetite for committed spend, and more aggressive packaging of “capacity + model + tooling” bundles to stabilize cashflows.
This also changes how to read “model competition.” The differentiator is increasingly who can secure compute with the least fragile capital structure, because that determines how reliably they can serve you at predictable latency and price.
The Risk: Debt-backed compute bets assume utilization. If demand softens, or if efficiency gains reduce required capacity faster than expected, the financing structure can become a constraint, forcing pricing moves that are about coverage ratios, not customer value.
Action:
- Map which products and workflows are exposed to inference price volatility, then quantify what a 25% and 50% step-up would do to gross margin.
- Push for pricing constructs that cap downside, committed-use discounts, multi-year rate cards, or workload-based ceilings, before your usage curve steepens.
- Add “provider cost of capital” to vendor diligence, ask directly how capacity is financed and what happens to pricing under refinancing stress.
RISK / LIABILITY
AI adoption is colliding with the insurance layer
Insurers warn AI claims may outpace existing coverage limits
The Wall Street Journal reports insurers are increasingly concerned that AI-related claims could outpace limits on existing coverage, as AI giants rack up potential legal liabilities in the tens of billions amid safety incidents, per Wall Street Journal.
This is the quiet constraint that shows up after the pilot succeeds, when procurement, legal, and risk committees ask who pays when something goes wrong.
The Bet: The next gating factor for scaled AI deployment is insurability, proof of controls, auditability, and incident response maturity.
So What? Operators should treat insurance as an adoption dependency, not a back-office detail. If underwriters tighten exclusions or raise premiums, the effective cost of deploying AI rises, especially in regulated and high-liability sectors. More importantly, insurance requirements tend to standardize behavior: logging, red-teaming evidence, model governance, and incident playbooks become table stakes because they are legible to risk capital.
This also creates a second-order market: vendors that can provide credible controls, traceability, and contractual clarity will reduce deal friction, even if their model isn’t the absolute best on a benchmark.
The Risk: The industry can over-correct into paperwork theater, controls that look good to underwriters but don’t reduce real incident probability. The other failure mode is coverage gaps discovered only after an event, when exclusions bite.
Action:
- Inventory where AI is already in production, then document controls in a format your insurer and your largest customers can read in one sitting.
- Run a tabletop incident exercise this month focused on AI-specific failure modes, data leakage, tool misuse, hallucinated actions, and unauthorized access via agents.
- Ask your broker what exclusions are emerging for AI claims, then align vendor contracts and internal policies to avoid uncovered scenarios.
INFRASTRUCTURE / SILICON
Memory bandwidth is becoming the bottleneck narrative
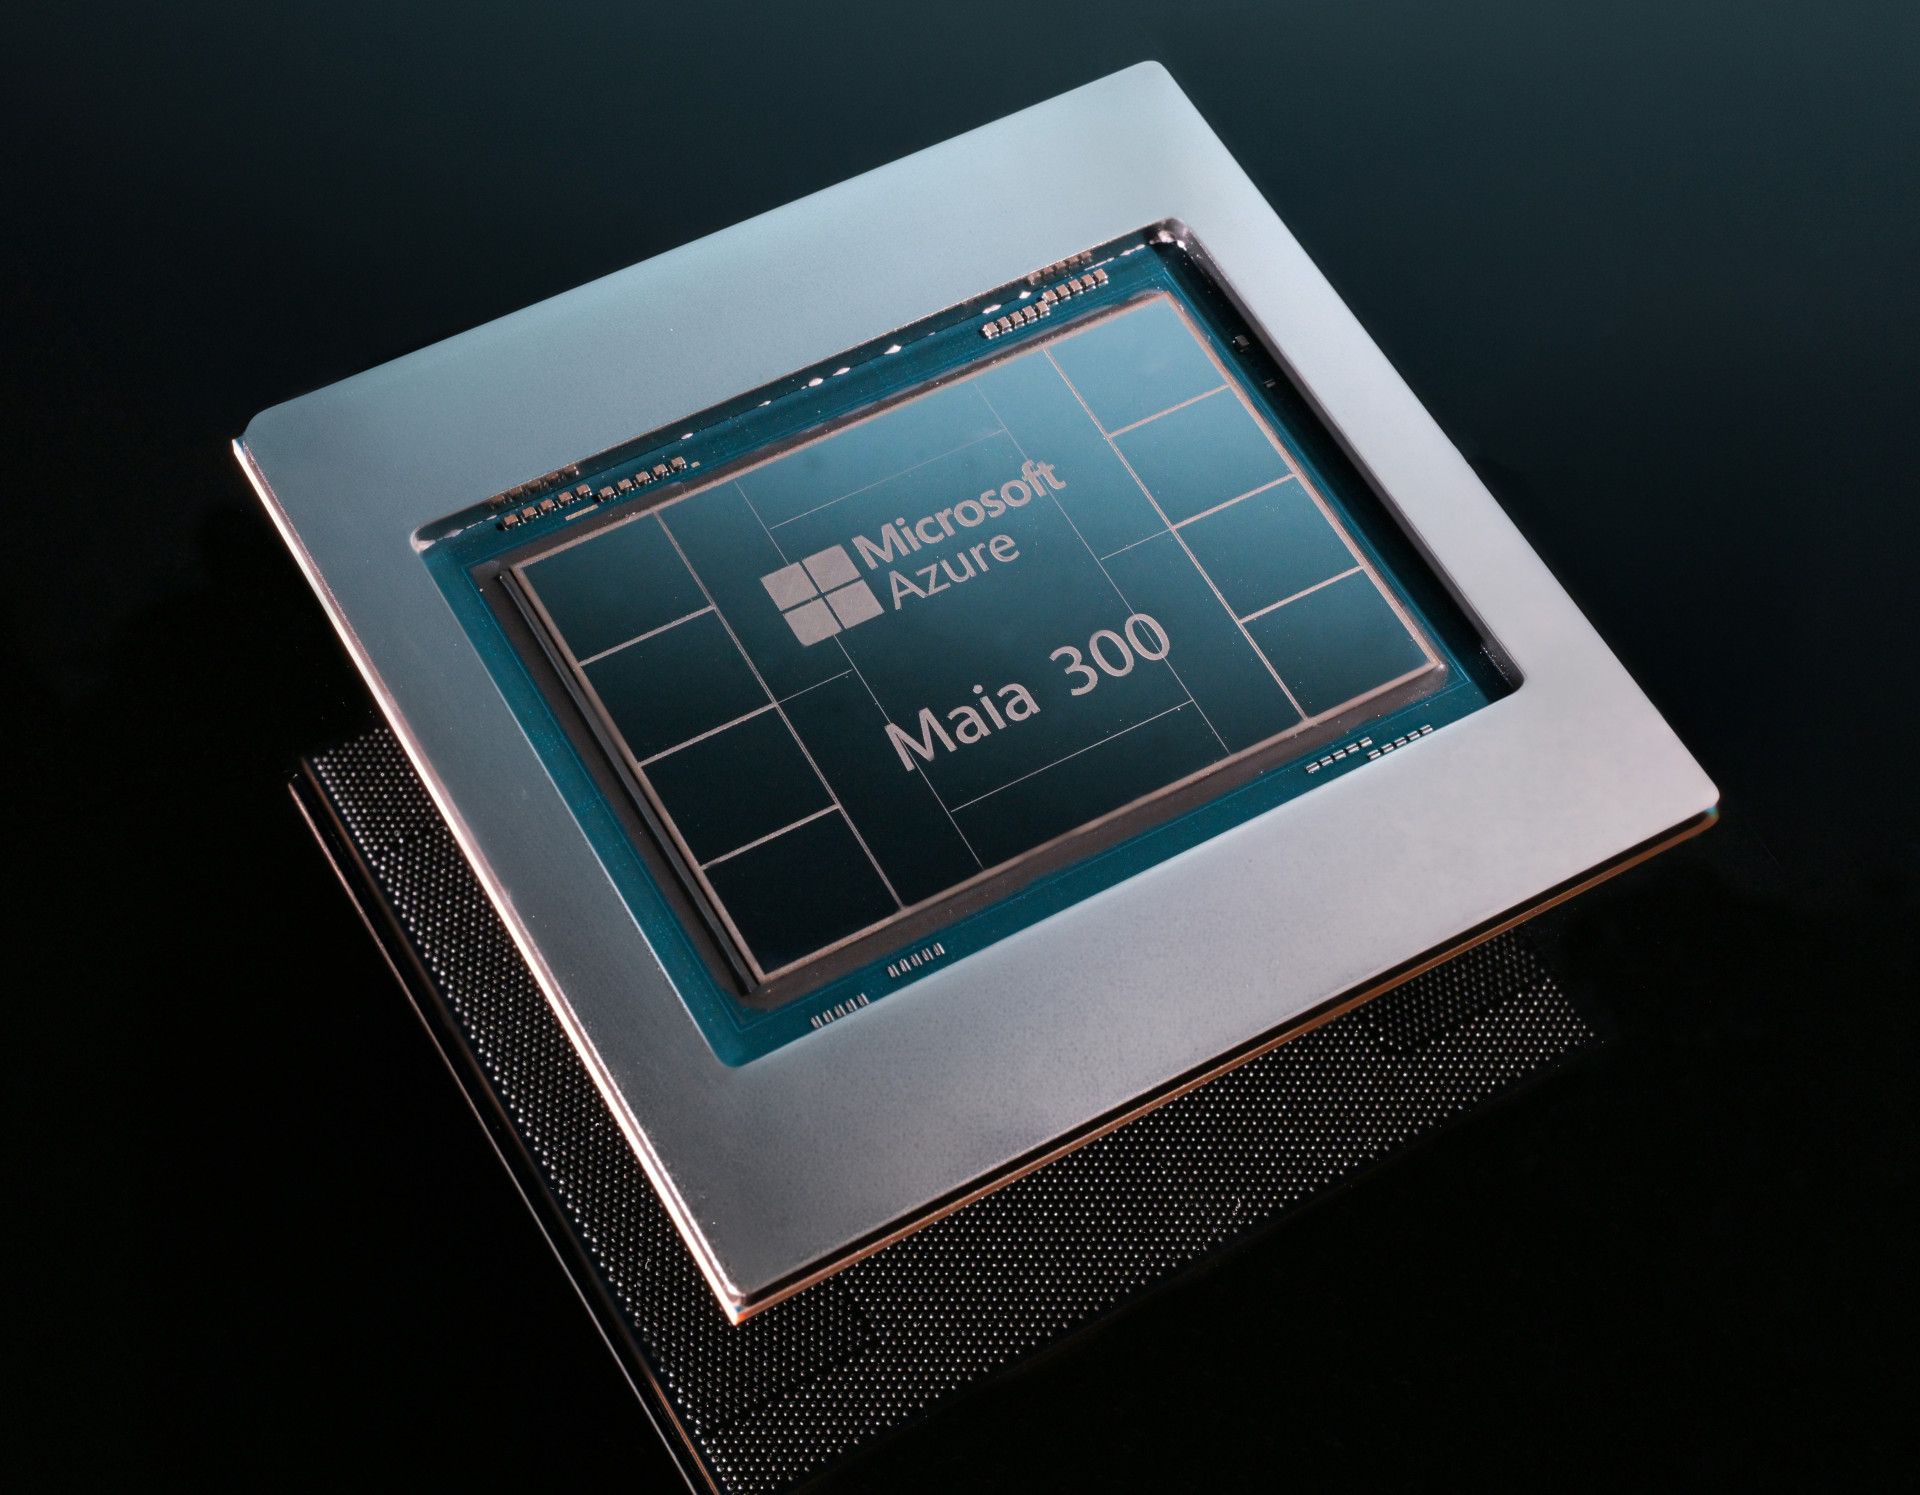
Microsoft’s Maia 300 emphasizes memory bandwidth and efficiency claims
TechRadar Pro reports Microsoft’s Maia 300 is swapping raw compute for a 2.5x memory bandwidth gain and claiming a 40% efficiency bump as Microsoft moves toward making in-house silicon its main AI engine, per TechRadar Pro.
Even if you discount marketing numbers, the directional point matters: the optimization target is shifting from “more FLOPs” to “feed the model” and “serve the workload” efficiently.
The Bet: The next infra advantage comes from system design, memory, interconnect, and software co-design, more than from headline compute.
So What? For operators, this is a warning against single-silicon assumptions. If your stack is tuned only for one vendor’s performance profile, you’re locking in both cost structure and supply risk. The practical implication is architectural: abstraction layers, kernel choices, quantization strategy, and model selection should be evaluated for portability across accelerators.
It also reframes procurement. The question is less “can we get enough top-tier GPUs” and more “what is our effective throughput per dollar for our specific models, context lengths, and latency targets.”
The Risk: Claimed efficiency gains often don’t survive contact with heterogeneous real workloads, especially when you include data pipelines, retrieval, tool calls, and post-processing. The other risk is organizational: teams underestimate the engineering cost of multi-accelerator support.
Action:
- Benchmark your top 3 production workloads on at least two hardware profiles, measure end-to-end cost per successful task, not tokens per second.
- Identify where your stack is brittle, custom CUDA paths, vendor-specific kernels, or model choices that don’t quantize cleanly.
- Negotiate contracts with exit ramps, avoid long commitments that assume a single accelerator roadmap.
CAPABILITY / MODEL ECONOMICS
“Better” is increasingly defined as faster and cheaper
DeepSeek releases an updated model it says is faster and leaner
Bloomberg reports DeepSeek pushed out an updated AI model it says is faster and leaner, per Bloomberg.
This is one more data point that the competitive frontier is not only about peak capability. It’s about usable capability under latency and cost constraints.
The Bet: The next wave of adoption is won on unit economics and integration friction, not on marginal benchmark wins.
So What? If “fast and lean” keeps improving, more workloads will move from “premium frontier endpoint” to “commodity model behind a product feature.” That changes build strategy: you can design for redundancy, route by task, and treat models as interchangeable components, if you’ve done the evaluation work.
It also creates pressure on vendors to justify premium pricing with governance, reliability, and enterprise-grade controls, because raw capability becomes less scarce.
The Risk: “Faster and leaner” claims can hide tradeoffs, tool reliability, long-context degradation, safety behavior, or multilingual performance. Operators who swap models without workload-specific evals will ship regressions.
Action:
- Build a routing harness now, define which tasks can fall back to cheaper models without breaking user trust.
- Create a lightweight eval suite tied to your product KPIs, latency, success rate, refusal behavior, and cost per completed workflow.
- Add a quarterly “model market scan” checkpoint, benchmark at least one non-default provider on your real prompts and tool chains.
SECURITY / THREAT OPERATIONS
Phishing is an industrial supply chain, not an inbox nuisance
Microsoft disrupts phishing kits tied to 1bn scam messages
Microsoft disrupted Chinese-language phishing kits, YAM Store, CoGUI, and Iron Man, linked to more than 1bn scam messages, per The Next Web.
The number matters less than what it implies: distribution at scale, packaged tooling, and market segmentation by language and region.
The Bet: The baseline threat environment is now “phishing-as-a-service” with professional operations and rapid iteration.
So What? Operators should assume phishing is a persistent background condition that will target the weakest operational link, contractors, new hires, regional teams, and any workflow that relies on email-based approvals. AI doesn’t need to create new threats to raise risk; it makes existing ones cheaper to personalize and easier to scale.
This also changes security ROI. The best returns come from hardening identity and approvals, MFA enforcement, device posture, and out-of-band verification for high-impact actions, because content-based detection will always lag.
The Risk: Takedowns are episodic. The underlying kit economy adapts, rebrands, and migrates. Organizations that treat this as a one-time spike will drift back into complacency.
Action:
- Audit your highest-risk workflows, password resets, vendor payment changes, payroll updates, and admin role grants, then add step-up verification.
- Segment training by region and language, phishing kits are localized; your defenses should be too.
- Tighten conditional access, require device compliance for admin actions and sensitive systems this week.
CONTRARIAN SIGNAL
The real AI bottleneck is becoming “risk throughput,” not model throughput
The market keeps narrating AI as a race for better models and more compute.
Yesterday’s evidence points to a different constraint stack: cost of capital, insurability, and operational controls. Those are throughput limiters. They determine how fast you can deploy, how broadly you can sell, and how much you can automate before your own governance becomes the bottleneck.
This is why the most “advanced” AI program in a company is often not the one with the best model access. It’s the one that can pass procurement, survive an audit, and explain its incident posture without hand-waving.
The Takeaway: If you want speed in 2027, build legible controls in 2026, because the organizations that can prove what happened will ship more than the organizations that can only demo what’s possible.
THE QUESTION FOR TODAY
Compute is being financed with infrastructure logic. Insurance is starting to price AI incidents as a real claims category. Model competition is tilting toward cost and latency, not just capability. Threat actors are operating at industrial scale with localized kits. Your AI roadmap is only as fast as your least mature dependency.
Where, specifically, is your AI program constrained right now, capability, capital, or custody?
Signal + Noise is strategic intelligence, not engagement-specific advice. For guidance calibrated to your org, start with Advisory.
See exactly how this impacts your specific industry and function. Upgrade to PRO to get bespoke tactical breakdowns generated instantly for your operating model.
Go deeper with the Weekly Signal
This is the daily take. The Weekly goes further — full strategic analysis across 8–10 sections, each with a signal read and operator action items. Source panel included.
Sign up free → then upgrade