
I gave Nvidia’s $8,000 RTX Spark mini PC a job, and now it works while I don’t
THE SO WHAT
An $8,000 RTX Spark mini PC chewing through 220,202 tokens in 13 minutes on repeat turns a desktop into a persistent inference appliance. If you’re architecting AI ops, treat high-end PCs as part of your compute fabric — with scheduling, monitoring, and security to match.
READ THE SOURCE
MORE FROM THE WIRE
 Applied AI
CoreWeave Says Nvidia Is ‘Not One Person,’ Remains a Key Partner
CoreWeave leaning in on Nvidia continuity is a reminder that your AI infra risk is institutional, not just about one executive. If you’re building on neoclouds, treat vendor concentration and leadership churn as a scenario to model — not a headline to ignore.
 Applied AI
Sources: ByteDance is in advanced talks with Microsoft to spend an additional ~$500M on Azure, primarily to access OpenAI models, drawing complaints from OpenAI
A ~$500M Azure deal from ByteDance primarily to access OpenAI models underscores how distribution and control over model access are now strategic levers for cloud. If you’re building on a lab via a hyperscaler, map where your provider’s commercial interests may diverge from the model vendor’s — that’s where policy changes can hit you with no notice.
 Applied AI
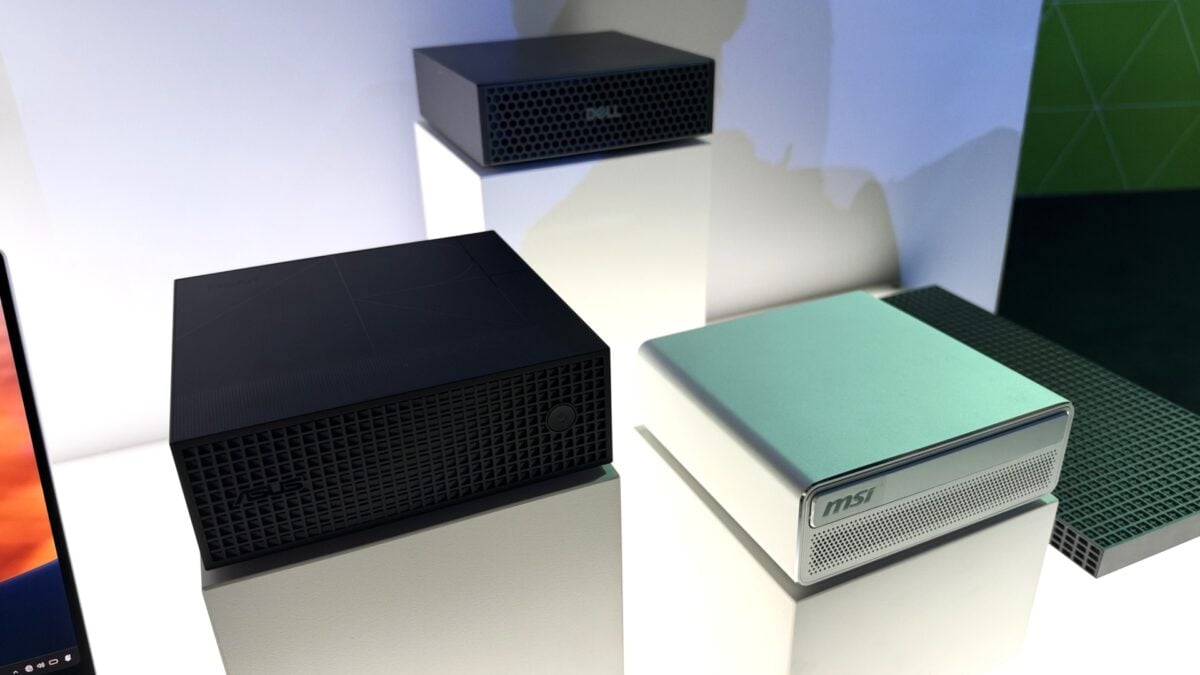
Nvidia’s RTX Spark Desktops Imagine They Can Actually Compete With the Mac Studio
RTX Spark desktops reframing AI spend as a one-time hardware purchase — $20 in power vs $1,200 in tokens — is a direct challenge to cloud-first inference economics. If your workloads are steady and heavy, you should be running the math on local GPU boxes versus API spend this quarter.
 Applied AI
Will Wright’s next game uses AI to map your memories
A mainstream game built around AI-mapped personal memories moves intimate data into entertainment — not productivity — contexts. If you touch consumer data, you need a position on how far you’ll go in modeling identity and memory, and what “opt-in” really means when the mechanic is the game.