
Jensen Huang wants Europe to dream bigger — with Nvidia’s help
THE SO WHAT
If Nvidia is publicly urging Europe to “dream bigger,” it’s a signal that the company sees underutilized demand for AI infrastructure on the continent. European operators should expect more aggressive courting on sovereign cloud, local data centers, and public–private capex deals—and should use that competition to lock in better economics and policy carve-outs.
READ THE SOURCE
MORE FROM THE WIRE
 Applied AI
Friends don’t let friends feed their data to AI agents
Consumer AI assistants that ambiently capture bystanders’ data without clear consent are creating a new privacy externality—your users’ friends and coworkers become the de facto attack surface. If your product records or transcribes shared spaces, you need an explicit policy and UX for third-party consent this quarter, or regulators and app stores will eventually write it for you.
 Applied AI
Nvidia launches Nemotron 3.5 Super VL, a 120B-parameter open model for enterprise agents, and says it outperforms frontier models on specialized benchmarks
A 120B-parameter, open Nemotron tuned for enterprise agents that can beat frontier models on narrow benchmarks is a direct nudge to keep high-value workflows on Nvidia’s stack—model, infra, and evals bundled. If you’re building agents for contracts, finance, or analytics, test Nemotron 3.5 Super VL against your current model this month and price in the lock-in vs performance trade.
 Applied AI
Bank of America had to hire 1,000 contractors to patch software flaws spotted by Anthropic Mythos
When an AI system forces a bank to hire 1,000 contractors and spend $100M+ to patch legacy flaws, the bottleneck isn’t detection—it’s remediation capacity. If you deploy AI code or security scanners at scale, budget for the downstream fix pipeline now or you’ll surface more risk than your org can realistically close.
 Applied AI
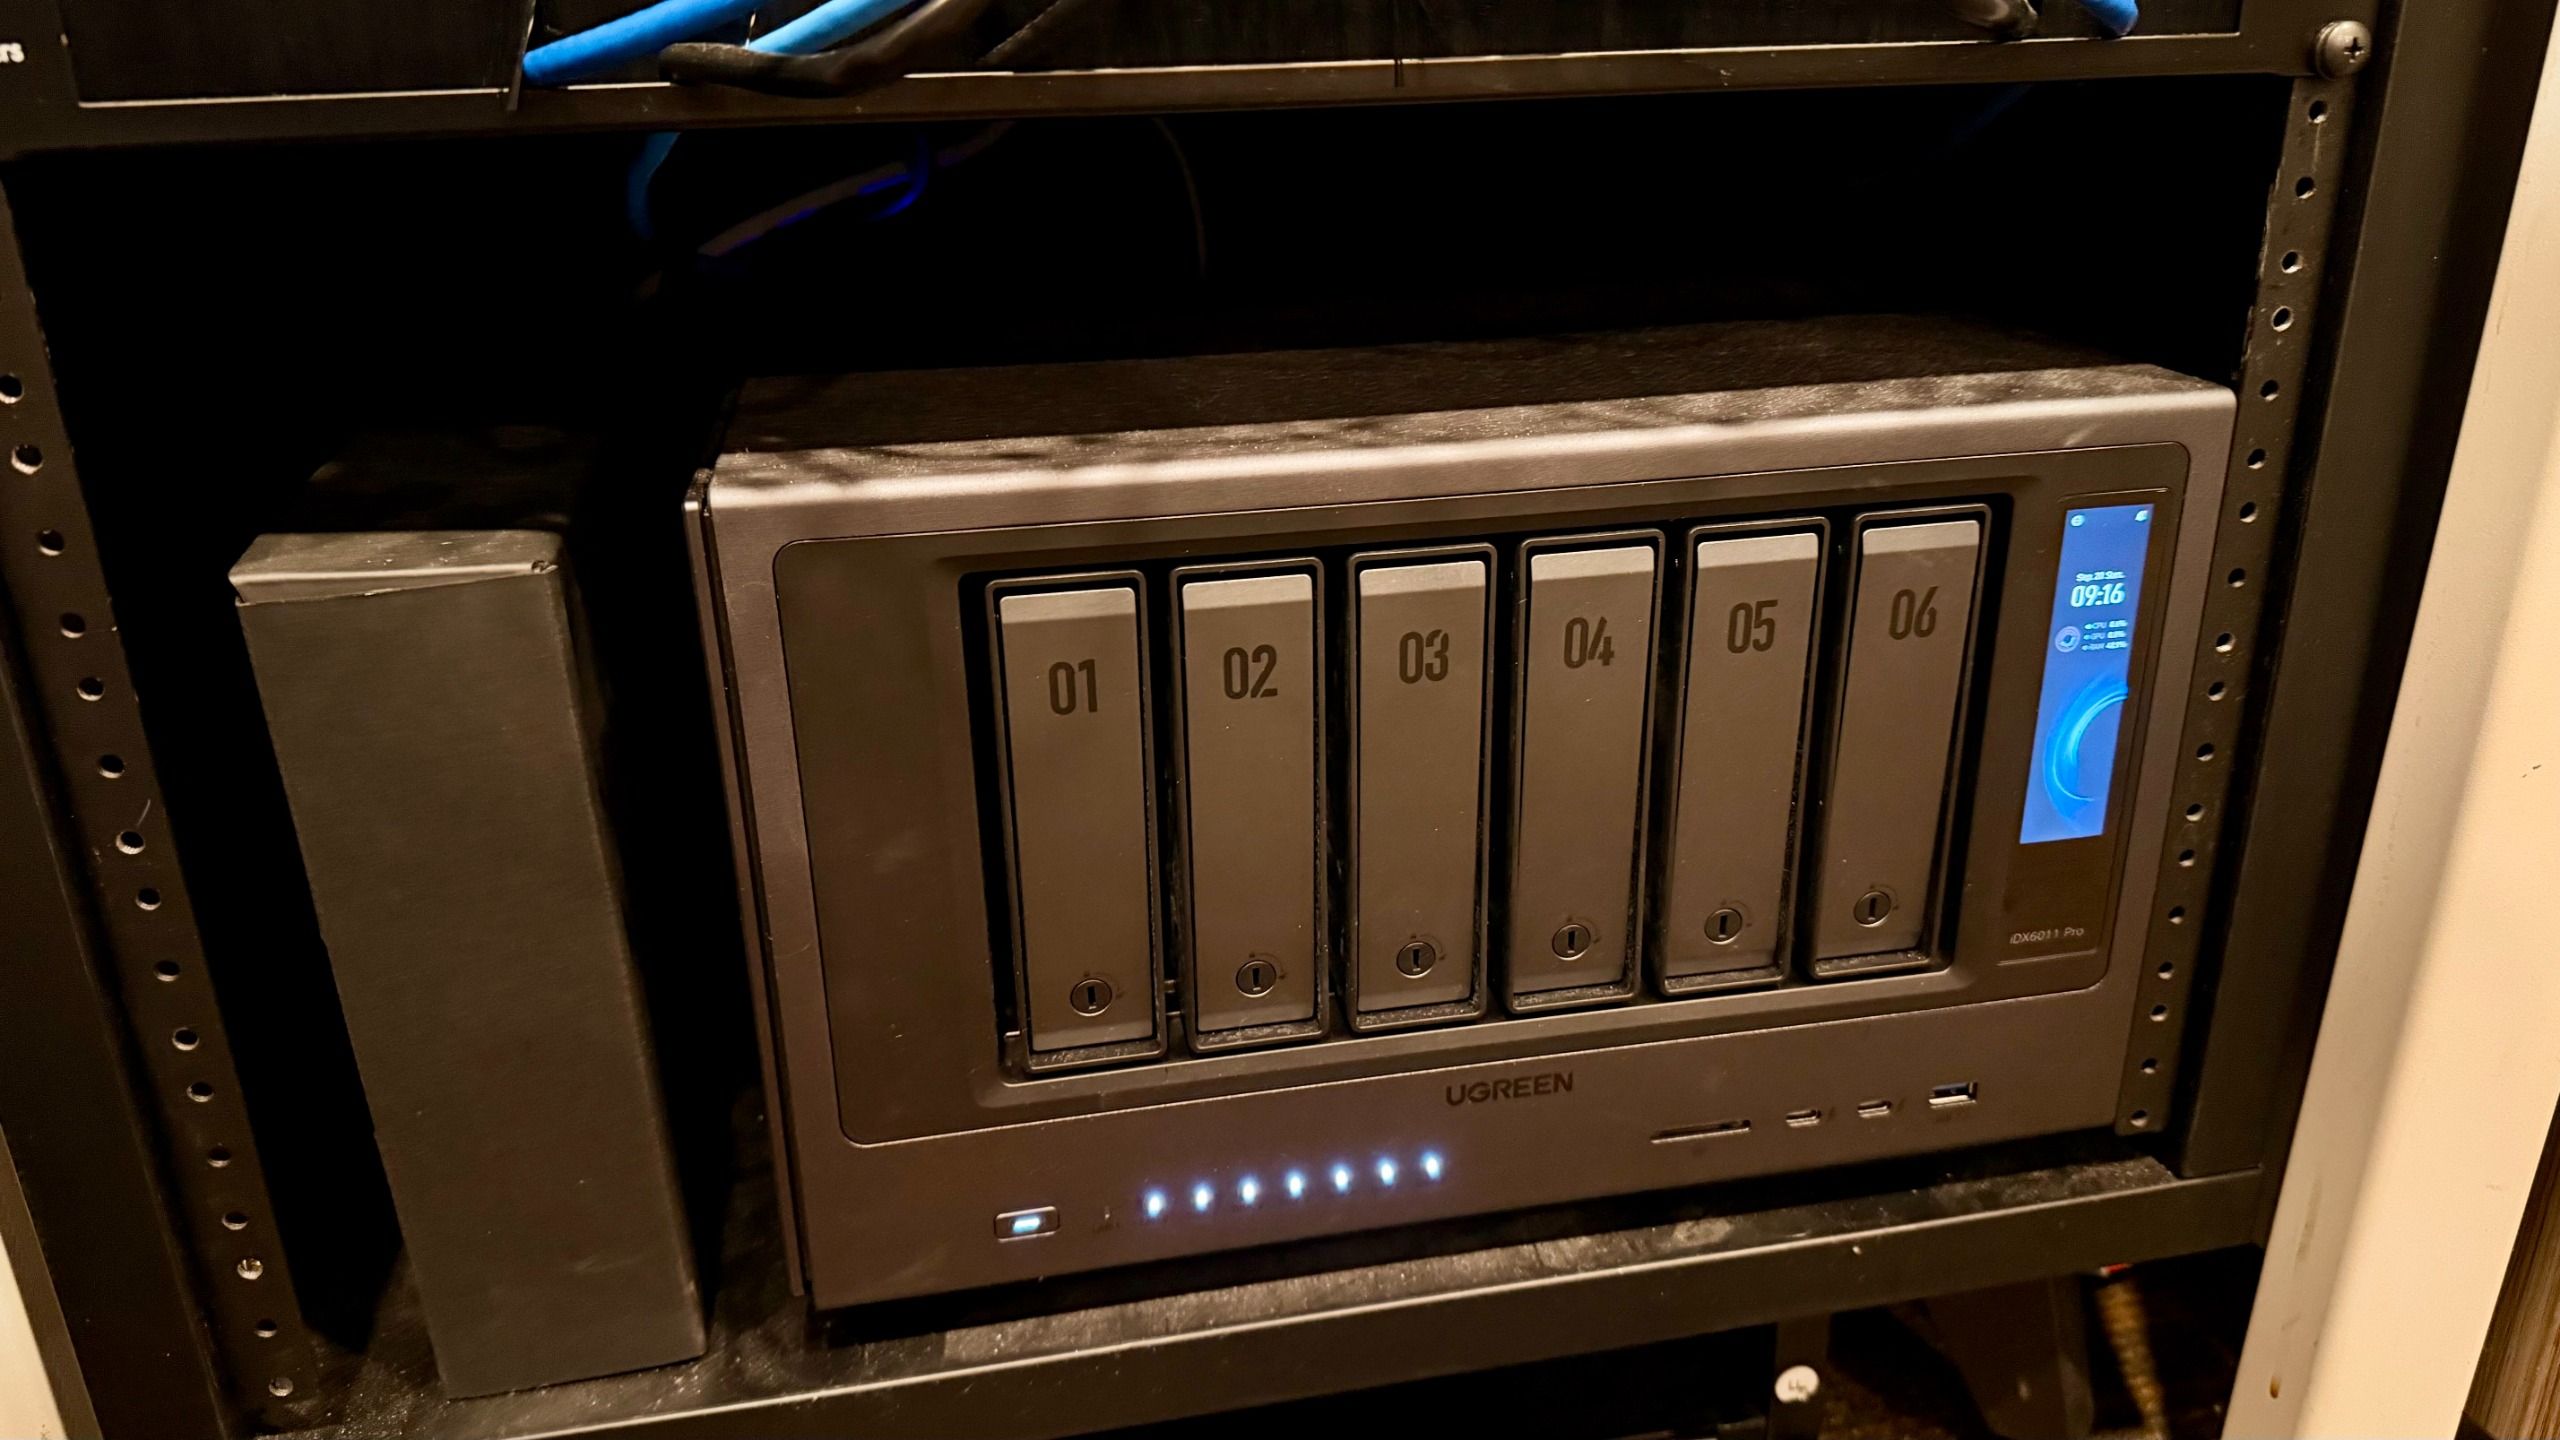
Ugreen NASync IDX6011 Pro NAS review
A NAS with an Intel Core Ultra 7255H, 64GB RAM, dual 10GbE, and onboard AI is basically a small on-prem inference box for creatives and SMBs. If you’re building AI workflows for media or design teams, assume more customers will want hybrid setups—local storage plus local models—with cloud used for burst and collaboration, not every inference.