
OpenAI Trumpet’s 3 More Math and Science Results, Along With a New Plan for Publishing Them
THE SO WHAT
Handing “major” math, CS, and physics results to external expert shepherds is OpenAI testing a new interface between frontier models and the scientific community. If you’re in a research-heavy domain, assume the bar is moving from ‘use AI as a tool’ to ‘design pipelines where AI proposes and humans formalize and publish.’
READ THE SOURCE
MORE FROM THE WIRE
 Applied AI
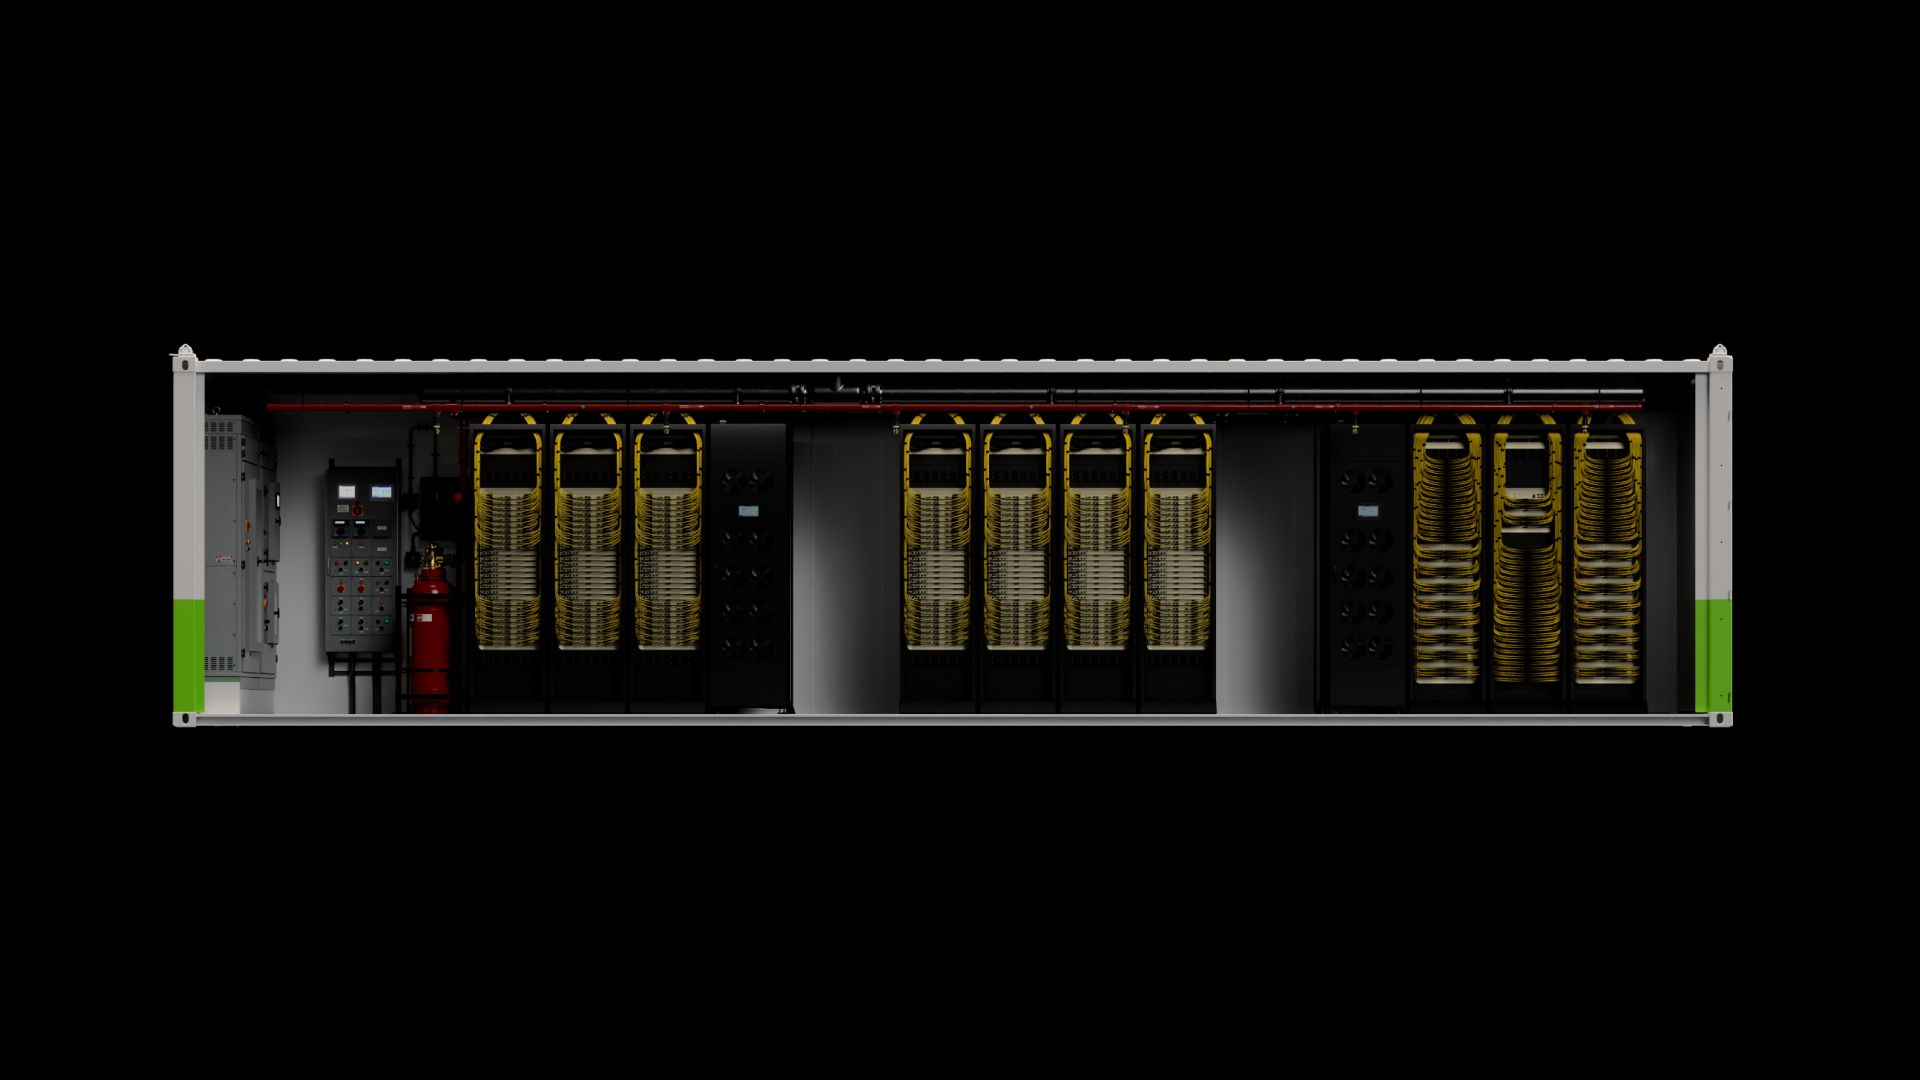
Nvidia reveals its mega DSX POD modular 'AI factory' — so could the latest Vera Rubin hardware actually help make data centers more energy efficient?
Nvidia’s DSX POD — Vera Rubin hardware in factory-built containers — pushes AI infra toward modular, shippable “plants” rather than bespoke data centers. If you’re planning large deployments, your edge is less about racking gear and more about securing sites, power, and integration talent for these pre-packaged AI factories.
 Applied AI
OpenAI announces three big science discoveries and a new way to work with academics
Moving from mass manuscript dumps to partnering with external experts on three “major” math, CS, and physics results is OpenAI professionalizing its role as a scientific actor. Universities and R&D orgs should assume that frontier labs will increasingly co-own high-impact results — and adjust collaboration, IP, and talent strategies accordingly.
 Applied AI
OpenClaw creator Peter Steinberger claims he spent $10 million in tokens in just a month — but luckily OpenAI can afford it
A single power user burning $10 million in API tokens in a month shows how quickly usage can concentrate and how volatile gross margins can be for model providers. If your product depends on third‑party tokens, you need hard rate limits, pricing levers, and unit‑economics alerts before a whale quietly rewrites your cost structure.
 Applied AI
Cross-request KV cache exposure in the GLM-5.3 Workers AI model (155 responses)
The KV cache exposure in Cloudflare’s GLM-5.3 Workers AI model is a concrete example of how performance optimizations can quietly become data-leak vectors. If you’re deploying shared inference infra, treat caching layers — KV, attention, embeddings — as security-critical surfaces and audit them like you would auth or storage.