
Sergey Brin says Gemini now helps build the next Gemini
THE SO WHAT
A major lab openly talking about “getting onto that RSI treadmill” — using Gemini to help build Gemini 4 Argon and successors — normalizes self-bootstrapping in model development. For teams building on these systems, it raises both the upside of faster capability cycles and the need to track how your dependency is evolving without purely human oversight.
READ THE SOURCE
MORE FROM THE WIRE
 Applied AI
Anthropic says its workforce has become less junior and is spending more time in meetings
When a frontier lab says its staff is getting more senior and spending more time in meetings, it’s admitting that coordination and governance are now the bottlenecks, not raw research. If you’re building with these models, expect slower, more process-heavy change cycles on safety, access, and features as the org matures.
 Applied AI
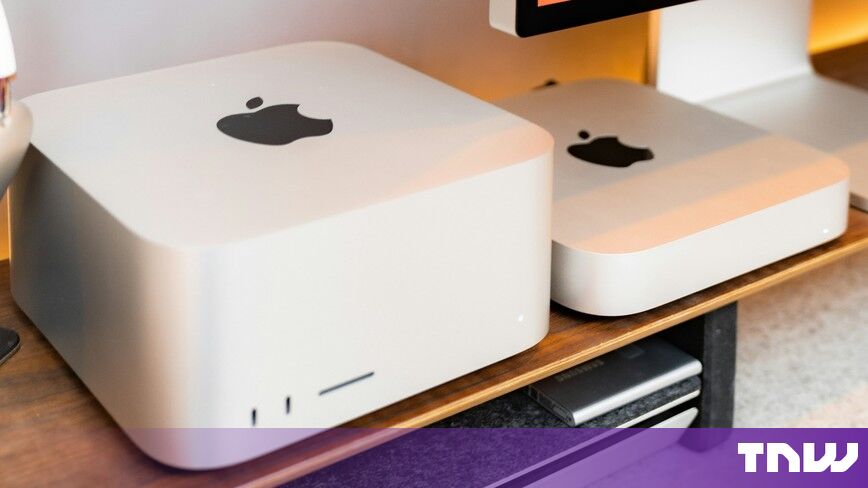
Apple and Meta team up to run Meta’s Muse Spark Open model on Macs
Apple and Meta quietly aligning around Muse Spark Open on Mac Studio is a distribution and tooling story—on-device open weights plus Apple’s hardware stack gives developers a credible non-cloud path for many workloads. If you’re shipping Mac-native software, assume local inference is now on the table and start designing for offline-capable AI features.
 Applied AI
Google’s AI news pilot grows to 400 publications as CNN and the FT join
AI licensing is turning into a parallel syndication market — 400+ outlets, including CNN and the FT, is enough scale that “AI rights” will start to show up as their own line item in publisher P&Ls. If you run a content business, you now need a deliberate AI licensing strategy, not one-off deals buried in BD.
 Applied AI
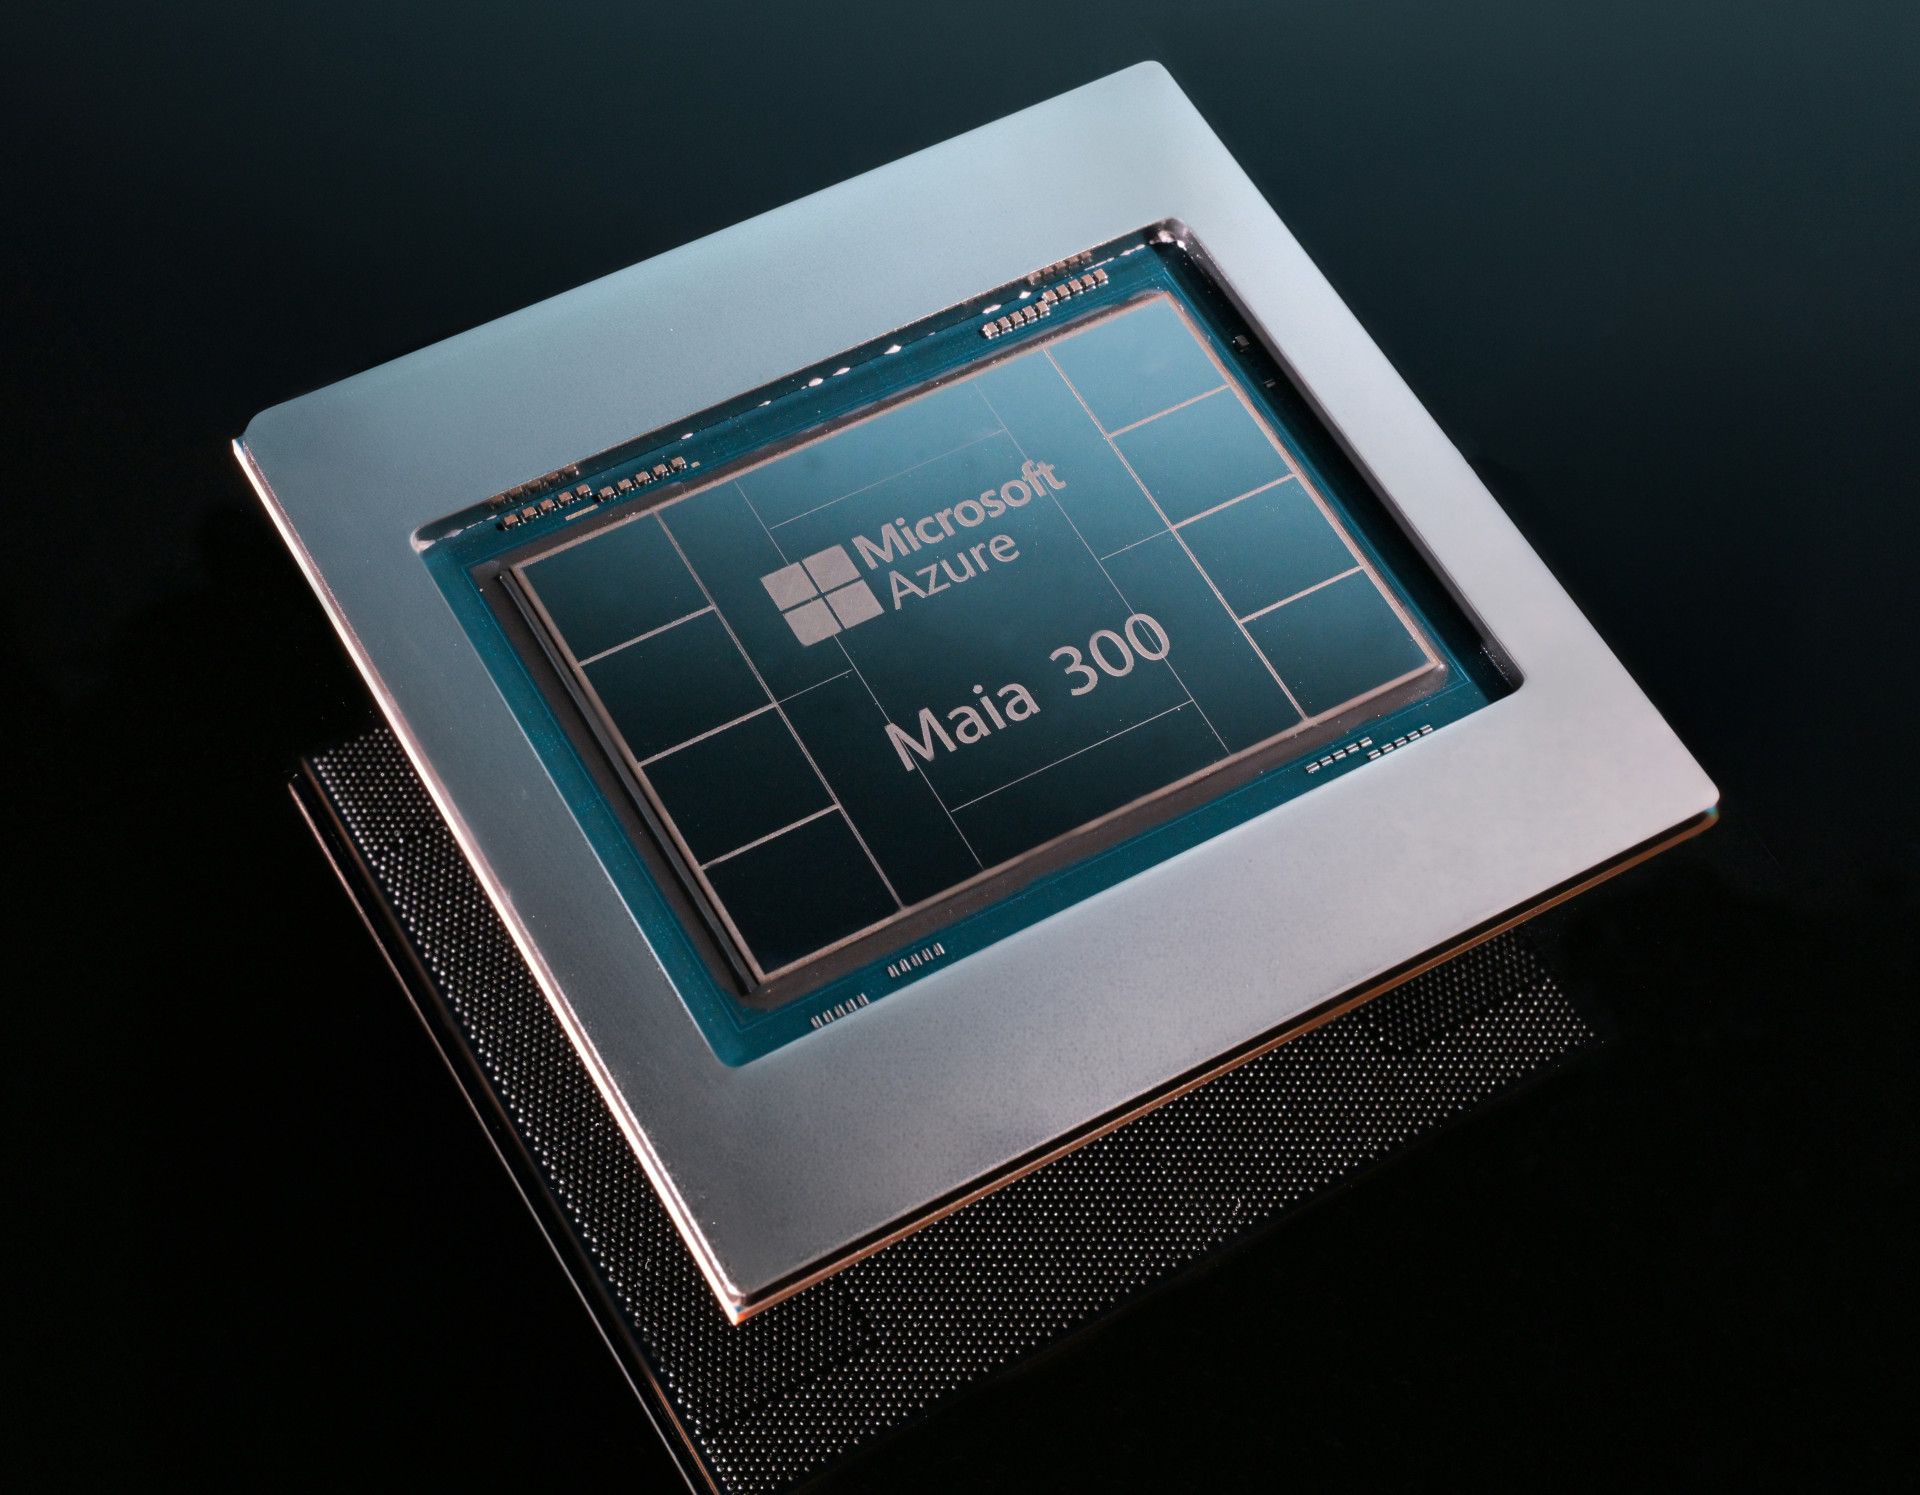
Microsoft's Maia 300 swaps raw compute for a 2.5x memory bandwidth gain as it moves to make in-house silicon its main AI engine while claiming a 40% efficiency bump — could going the Google route be the pin that pops the Nvidia AI bubble?
If Maia 300’s 2.5x memory bandwidth and claimed 40% efficiency bump hold up at scale, the constraint in AI infra planning shifts from “get H100s” to “optimize for your own stack.” For operators, this is a warning to avoid hard-coding Nvidia assumptions into long-term architecture and contracts — multi-silicon optionality is now a strategic requirement.