
Show HN: Corgi, a helpful {agent, terminal} multiplexer
THE SO WHAT
Agent multiplexers wired into the terminal are turning shell workflows into orchestrated multi-agent systems — the UX frontier is shifting from single-chat assistants to persistent, observable agent swarms. If your team lives in the CLI, piloting tools like this now will tell you where agentic automation actually sticks in day-to-day ops.
READ THE SOURCE
MORE FROM THE WIRE
 Applied AI
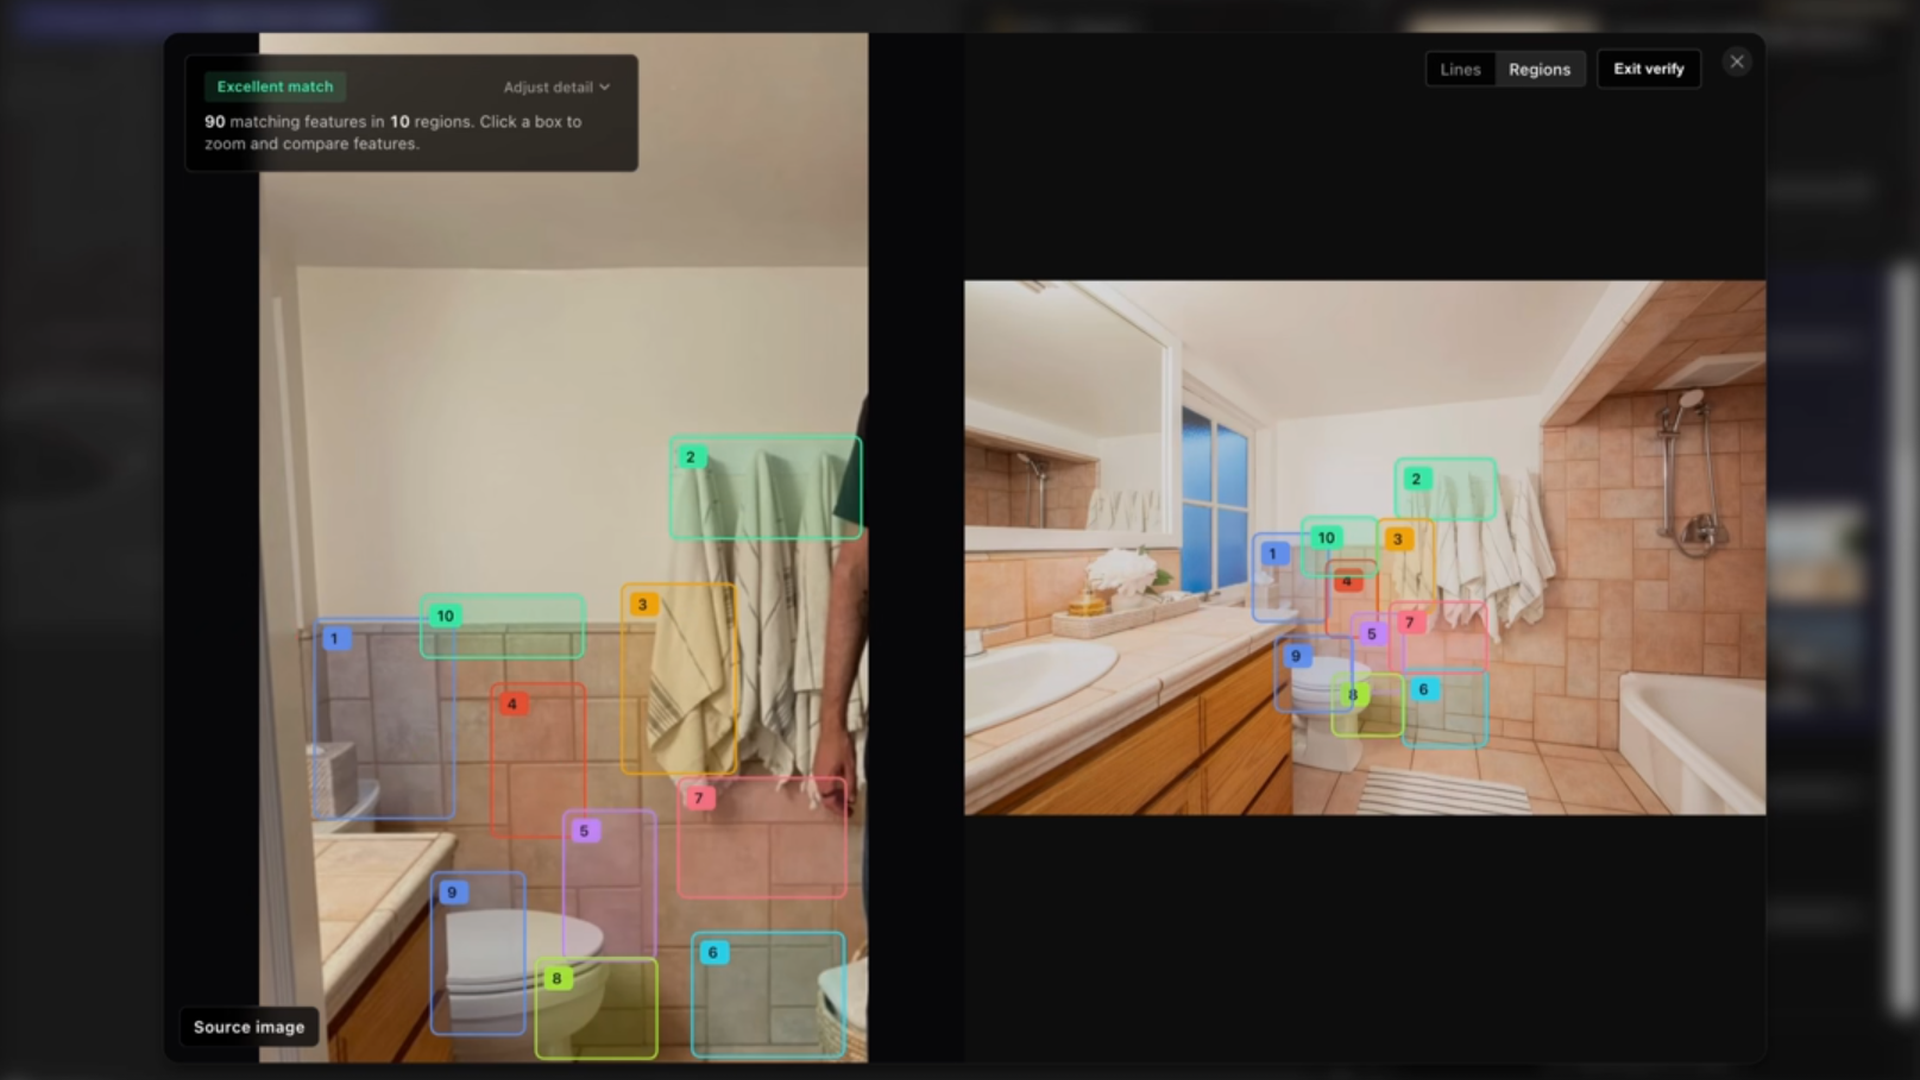
This AI tool can now turn ordinary household photos into location clues — so could law forces use the technology to scope out your home?
If interior photos can be reliably geolocated, every product shot, listing image, and social post becomes latent location data. Map your exposure: marketing, real estate, and marketplace teams need a policy on what gets photographed and how it's stored before this capability becomes commoditized.
 Applied AI
OpenAI says it will no longer train its AI models on the live internet, citing “significant risks”
Cutting frontier models off from the live internet pushes the ecosystem toward curated, slower-moving corpora and proprietary data partnerships. If you’re counting on real-time web grounding as a differentiator, assume more friction, higher licensing costs, and tighter safety scrutiny around whatever you scrape or stream.
Mark Cuban says the best defense against malicious AI agents is more AI
Framing malicious AI agents as “cockroaches” implies an arms race where manual defense is structurally outmatched. CISOs and infra leads should budget for autonomous or semi-autonomous defense systems — detection, triage, and response — rather than assuming human-centric SOC workflows will scale.
 Applied AI
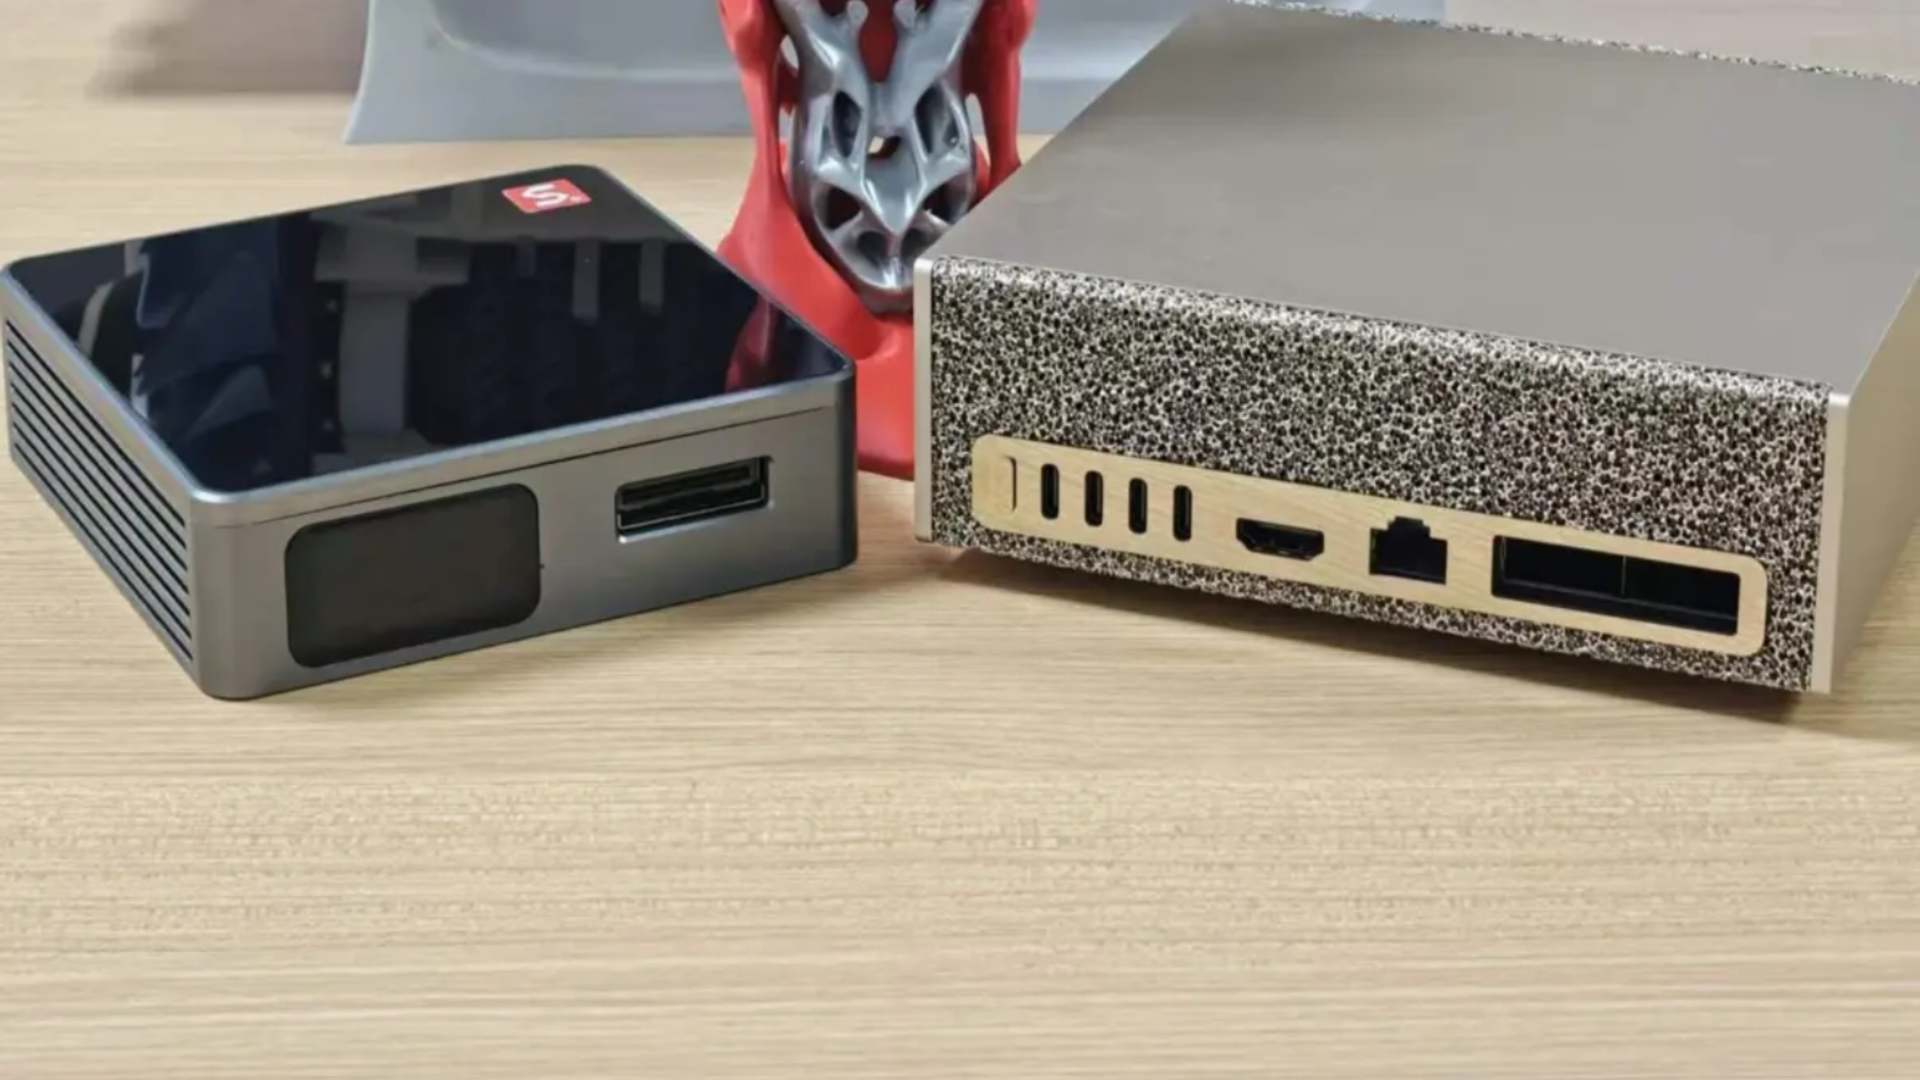
Plucky Chinese startup claims to beat Nvidia DGX Spark, Mac Mini on Qwen — says its '256 TOPS beats 1000 TOPS in prefill', running 16-core Cortex-A55 SoC on 40w
If a 40W, 256-TOPS Cortex-A55 box can credibly beat a DGX Spark on specific Qwen prefill workloads, TOPS is now marketing, not an engineering proxy. Infra teams need to benchmark on end-to-end tokens-per-watt and latency for their own models, not on vendor headline specs.