
'The GPU never reads the same text twice': Belgian startup Corbenic wants to turn your server's SSD into AI memory, but its 14x speedup owes more to reading less
THE SO WHAT
The real story in Corbenic’s claimed 14x speedup is not magic SSDs as “AI memory” but smarter cache reuse and avoiding redundant GPU reads. For teams running vLLM, SGLang, or Llama.cpp at scale, the next efficiency frontier is software-level KV cache orchestration across cheap storage tiers, not just buying more HBM.
READ THE SOURCE
MORE FROM THE WIRE
 Applied AI
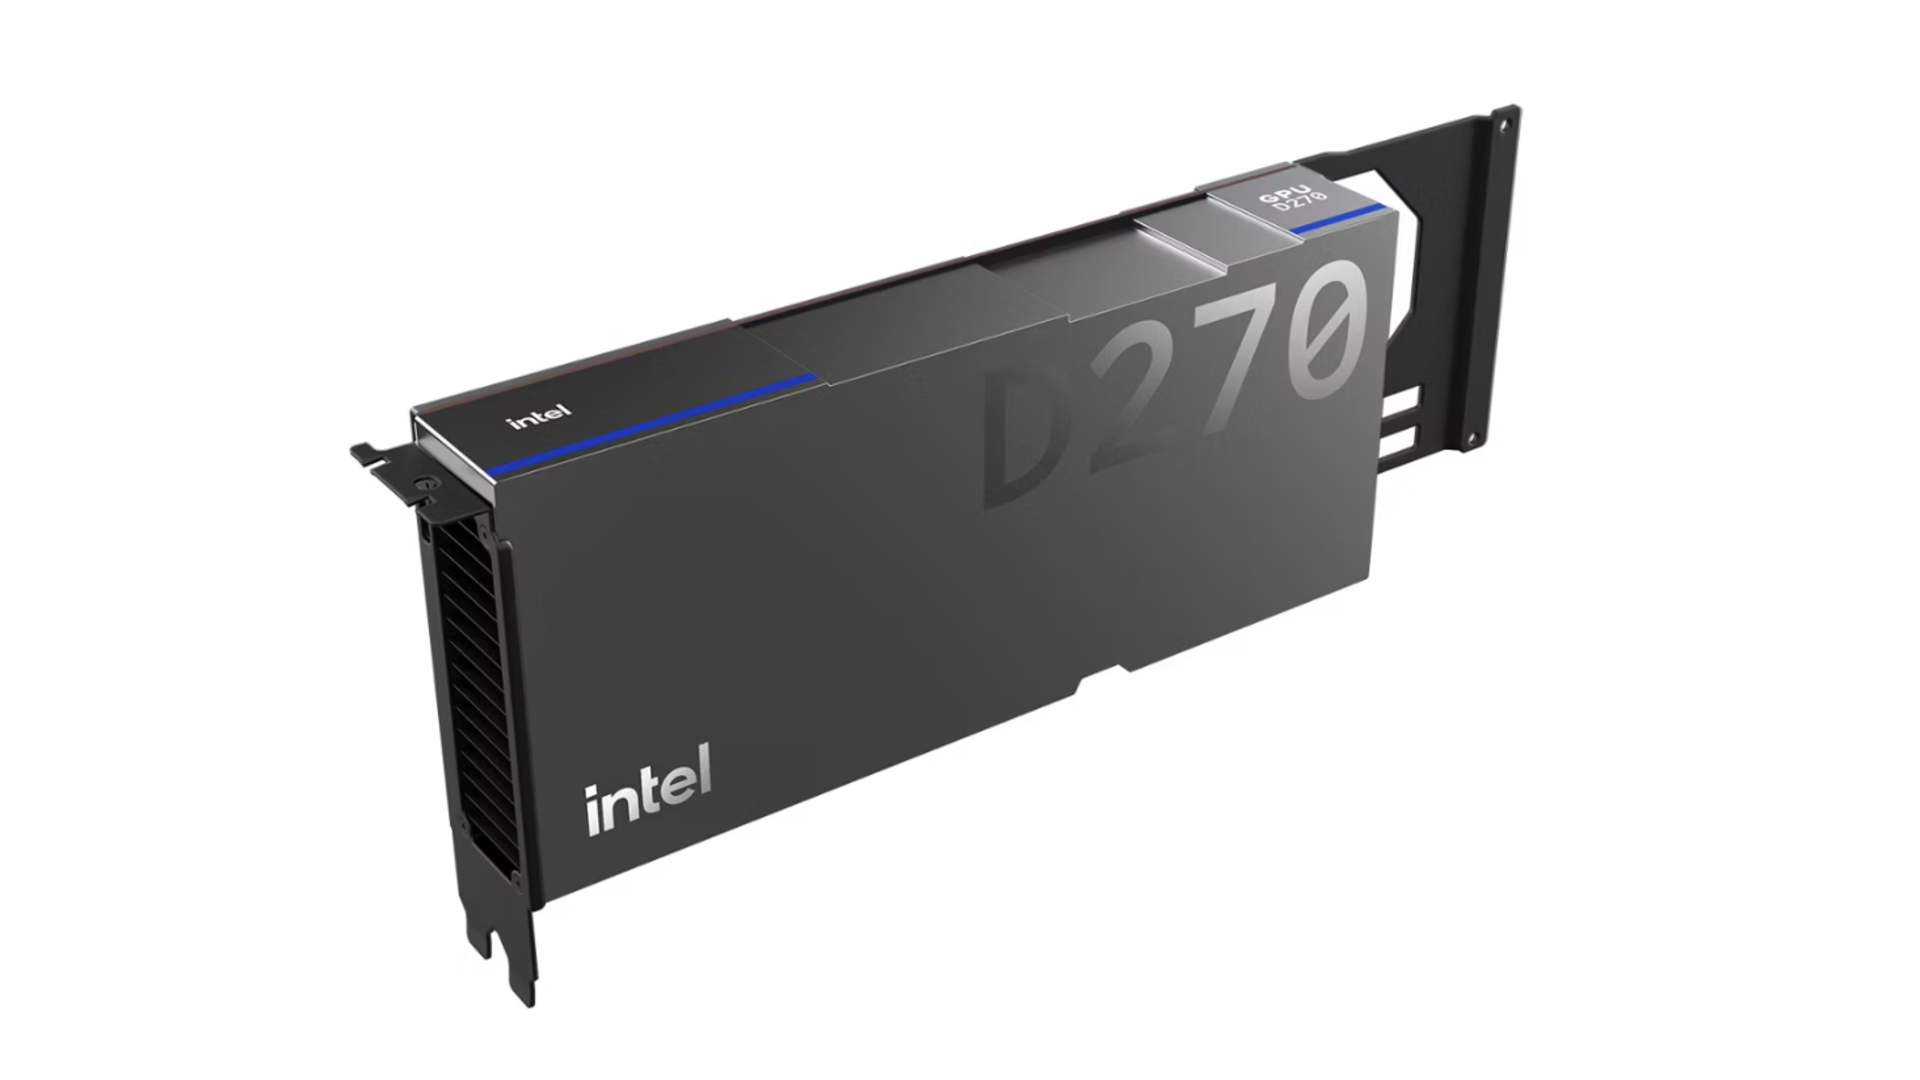
Behold, Intel plans a 480GB GPU, a video card with more memory than the average laptop SSD has storage — but of course it's for AI, and curiously, it will use LPPDR5X, not even GDDR7
A 480GB, 1.3 PFLOP FP8, 350W GPU built on LPDDR5X is a bet that memory capacity and energy efficiency will matter more than raw peak bandwidth for many AI workloads. If you’re planning model architectures or infra spend, assume the next wave of accelerators will let you keep far larger models and contexts on a single card—simplifying scaling patterns but changing your cost/performance assumptions.
 Applied AI
Anthropic is pitching Congress its own AI safety bill, report says
A lab privately drafting an AI safety bill that narrows federal stop powers and preempts some state rules is a move to shape the regulatory perimeter while it’s still fluid. If you build on frontier models, expect compliance to hinge less on generic AI law and more on the specific governance regimes your model vendors succeed in getting codified.
Anthropic commits billions to a 'public benefit fund'
Putting company stock into a charitable LLC hardwires a parallel power center into Anthropic’s cap table — future governance fights won’t just be between investors and management. For operators, this is another data point that AI labs are experimenting with ownership structures as much as model architectures, which may influence how you think about long-term alignment, partnership risk, and who actually controls the roadmap.
 Applied AI
Disney agrees to hire the majority of Character.AI’s workforce
Disney absorbing most of Character.AI’s team under its new CTO is a clear move to internalize conversational and character AI as core IP, not vendor spend. If you own a large consumer brand or universe, expect pressure to build in-house narrative and persona AI capabilities rather than relying solely on off-the-shelf assistants.