
Underdog shows off a 32MB speech model in new demo
THE SO WHAT
A 32MB model that can generate speech and music pushes high-quality audio into true edge territory — phones, wearables, toys, cars. If your product assumes cloud-only TTS or music gen, revisit latency, privacy, and offline modes as near-term differentiators.
READ THE SOURCE
MORE FROM THE WIRE
 Applied AI
Partnering with Edelbyte: Data Infrastructure That Keeps Up With AI's Curiosity
If agents are going to hammer your internal systems with orders of magnitude more queries than humans ever did, the real constraint becomes data infra cost and latency, not model quality. Teams building agents should be budgeting for a new class of OLAP-style infra like Edelbyte’s, not assuming the existing warehouse can take the load.
 Applied AI
AI is the new dating dealbreaker
AI use is becoming a values filter in consumer relationships—people are screening for how much their matches lean on AI in daily life. Expect similar preference sorting to show up in hiring, brand affinity, and community design as AI habits become part of identity.
Applied AIBrookfield’s Teskey Calls ‘Social License’ Crucial for AI Growth
When a major infra allocator says social license is now prerequisite for AI builds, community consent becomes a core part of the project finance stack. If you’re planning data centers or large AI deployments, budget for local engagement the way you budget for transformers and cooling.
 Applied AI
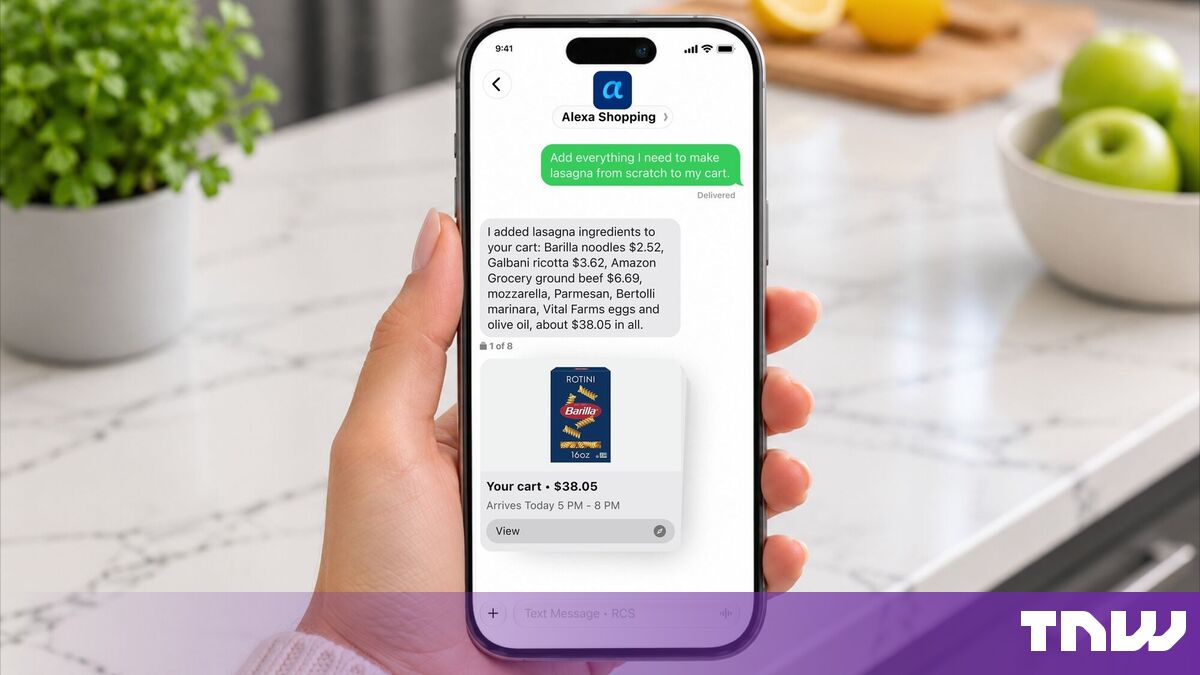
Amazon’s Alexa for Shopping agent will now take your orders by text
Texting Alexa for Shopping turns the AI agent into a persistent, low-friction commerce surface—with sponsored products already wired in. Brands now have to think about how they show up in conversational rankings, not just search and display.