
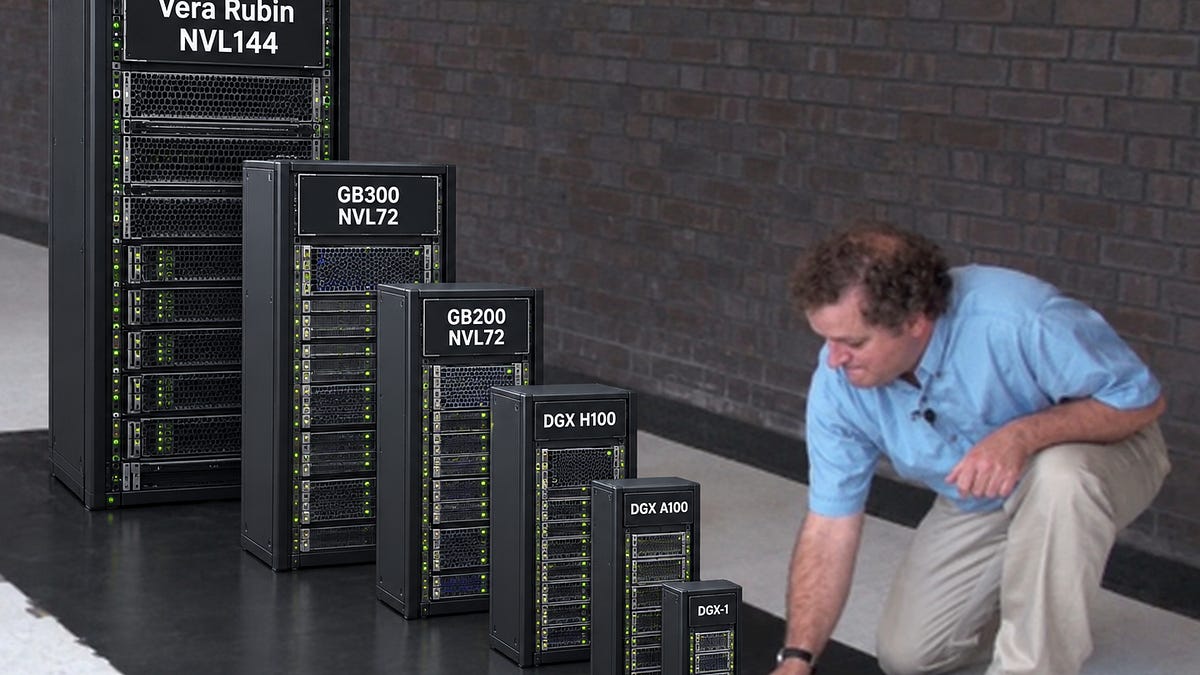
Vera Rubin NVL72 inference tests show up to 7x better token throughput per MW vs. Blackwell on a 1.6T DeepSeek model, above Huang's 3x claim for 1T-3T LLMs
THE SO WHAT
If Vera Rubin NVL72 is delivering ~7x better tokens per MW on a 1.6T model than Blackwell, the constraint for frontier inference shifts even harder toward power and systems engineering. For anyone budgeting large-scale agentic workloads, model choice now has to be co-optimized with energy contracts and datacenter design, not just GPU count.
READ THE SOURCE
MORE FROM THE WIRE
 Applied AI
Google DeepMind Staffer Says AI May ‘Kill Us All’ in Exit Post
High-profile safety concerns from inside labs keep existential risk in the Overton window, which raises the odds of sharper, more binary regulatory moves rather than quiet, incremental rules. Leaders deploying advanced models should treat this as policy volatility risk—build optionality into vendors, model classes, and jurisdictions.
 Applied AI
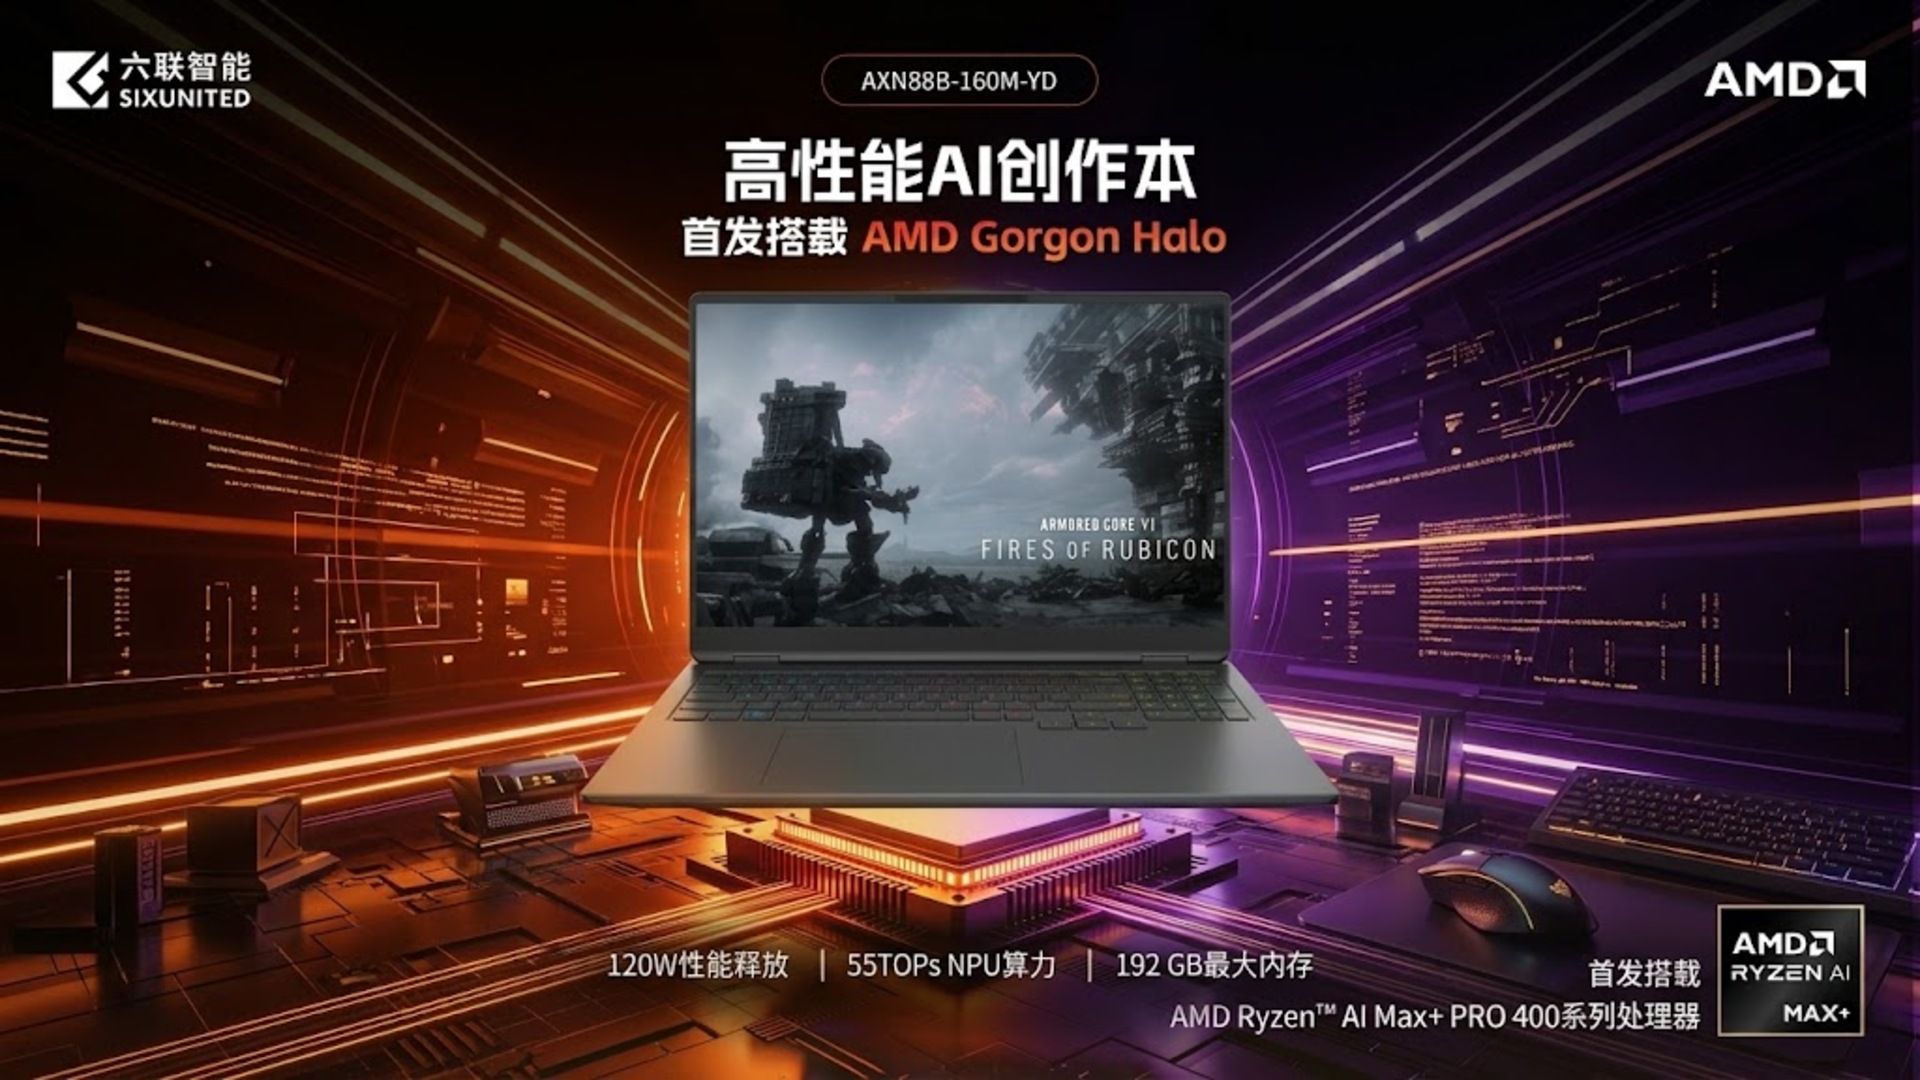
Chinese vendor debuts world's first AMD Ryzen AI Max+ Pro 495 laptop, but 192GB LPDDR5X-8533 for gaming? Really??
A 192GB Ryzen AI Max+ Pro 495 laptop is a workstation in gaming clothing—this is about local model fine-tuning and heavy inference, not frame rates. If you're building for power users, assume a growing slice will have “AI rigs” on the desk and design workflows that can exploit local + cloud together.
Applied AIThoughts on AI labs' safety concerns: a coordinated slowdown may look like an antitrust conspiracy to limit output that would preserve frontier model margins
If labs coordinate on “safety slowdowns,” regulators may read it as output restriction to protect frontier margins rather than altruism. For operators, that means AI supply, pricing, and release cadence are now entangled with antitrust risk—treat long-term model access as a regulatory, not just technical, dependency.
 Applied AI
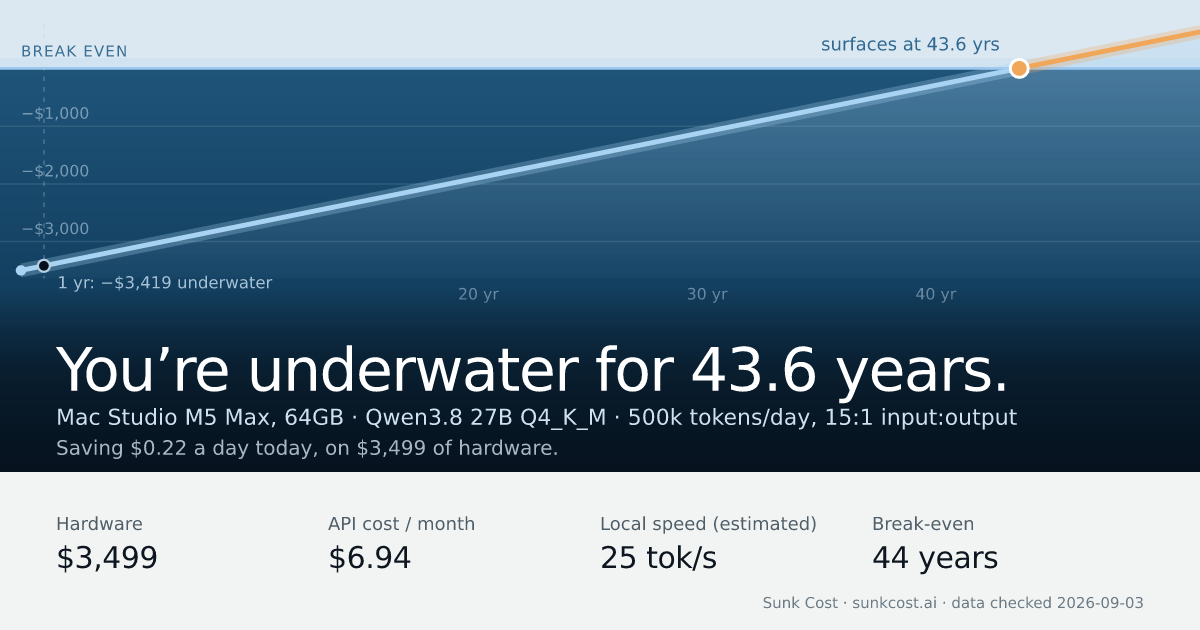
Show HN: Sunk Cost – How long until a local LLM rig pays for itself?
A public calculator for local vs. API LLM economics means more teams will run the numbers instead of defaulting to cloud. If your token spend is material, you should already be modeling breakeven on local rigs and planning for a hybrid architecture where it pencils out.