
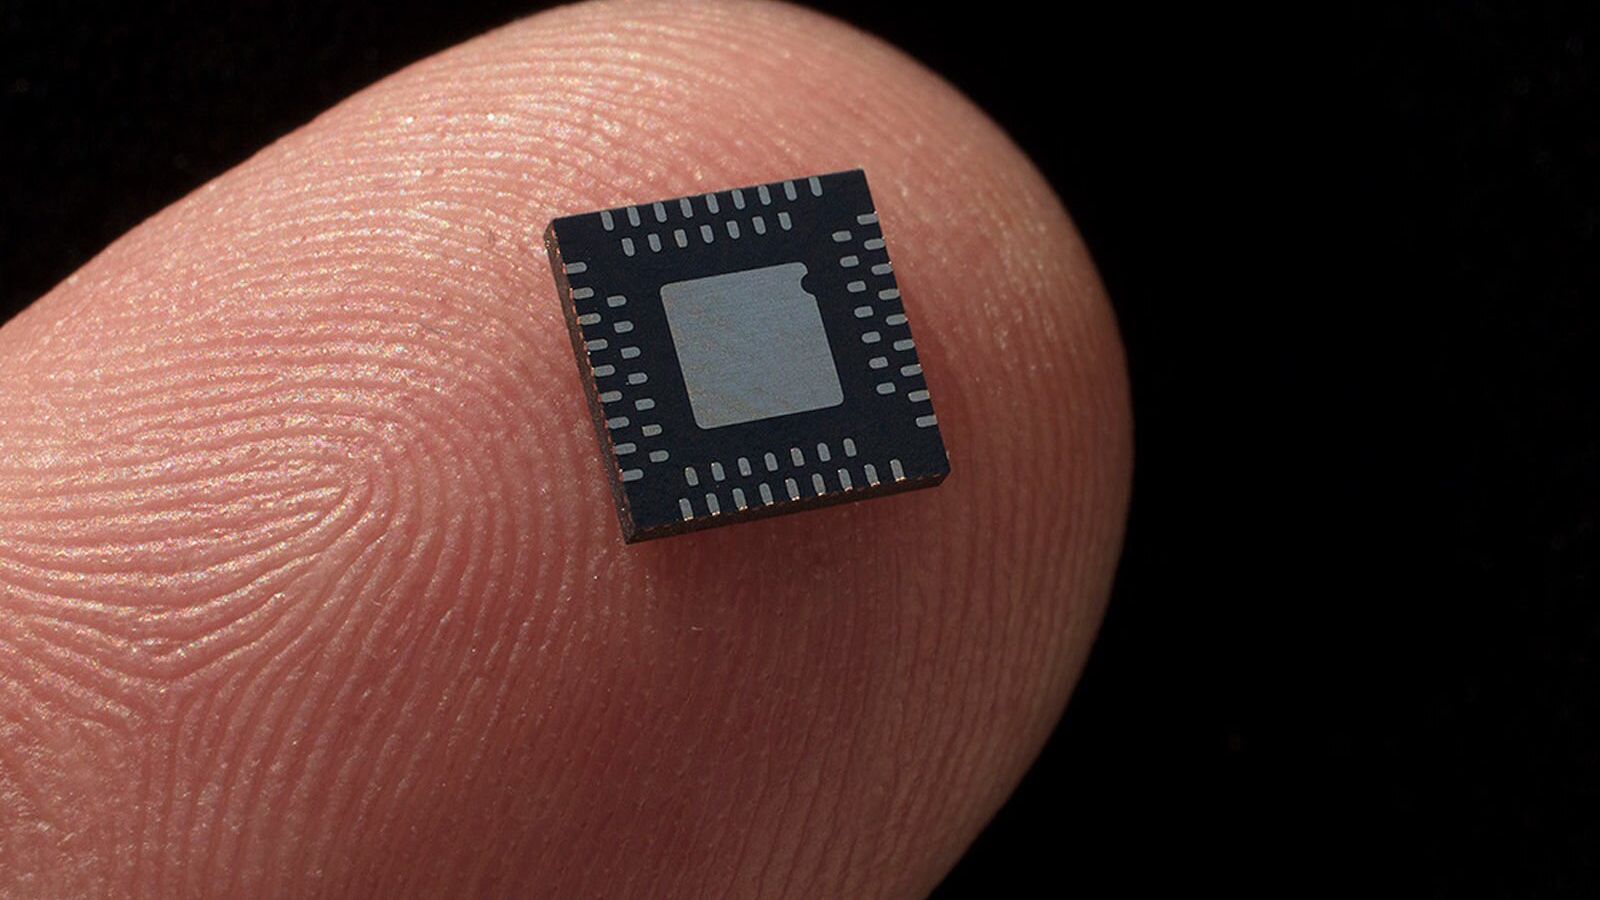
Arm AGI CPU crushes AMD in new agentic AI benchmark — but what does its 2x rack-level performance advantage mean for the future of x86 data centers?
THE SO WHAT
If Arm’s AGI CPU really delivers ~2x rack-level performance on agentic AI workloads, x86 lock-in for inference-heavy data centers starts to weaken. Infra teams planning 2026–2028 buildouts should model TCO and power for Arm-based AI racks now—before renewing long-dated x86 commitments.
READ THE SOURCE
MORE FROM THE WIRE
 Applied AI
AI Will Empower India's Space Missions, Says Minister
India is explicitly tying AI to its next phase of nuclear and space programs—expect more dual-use AI investments that blend civilian space, defense, and energy. For vendors and partners, this means AI infra and tooling deals in India will increasingly be evaluated through a strategic, not just commercial, lens.
Applied AIMeta Says Claude AI Tool Triggered No Kings Instagram Suspension
Automated trust-and-safety that can pull down an activist account at the peak of demonstrations is now a material reputational and policy risk, not just a UX bug. If your product touches speech or organizing, you need explicit escalation paths and human review thresholds for high-sensitivity entities before you scale AI moderation further.
 Applied AI
'The GPU never reads the same text twice': Belgian startup Corbenic wants to turn your server's SSD into AI memory, but its 14x speedup owes more to reading less
The real story in Corbenic’s claimed 14x speedup is not magic SSDs as “AI memory” but smarter cache reuse and avoiding redundant GPU reads. For teams running vLLM, SGLang, or Llama.cpp at scale, the next efficiency frontier is software-level KV cache orchestration across cheap storage tiers, not just buying more HBM.
Applied AIIf you don't run your own LLM proxy, how do you know whats going on?
The push to run your own LLM proxy reflects a deeper shift from "use the API" to "instrument the entire inference path"—observability, routing, and policy are becoming first-class concerns. If you’re spending real money on LLM calls, stand up at least a thin proxy layer this quarter so you control logs, latency, model choice, and safety filters instead of outsourcing them blindly.