
OpenAI Projects Burning Through $278 Billion by 2030
THE SO WHAT
If one lab is modeling nearly $300B of cash burn through 2030, hyperscalers, chipmakers, and power providers are implicitly underwriting that risk—your AI roadmap is now entangled with their balance sheets. Operators should assume rapid iteration in pricing, packaging, and partnership terms as these capital plans collide with real demand.
READ THE SOURCE
MORE FROM THE WIRE
 Applied AI
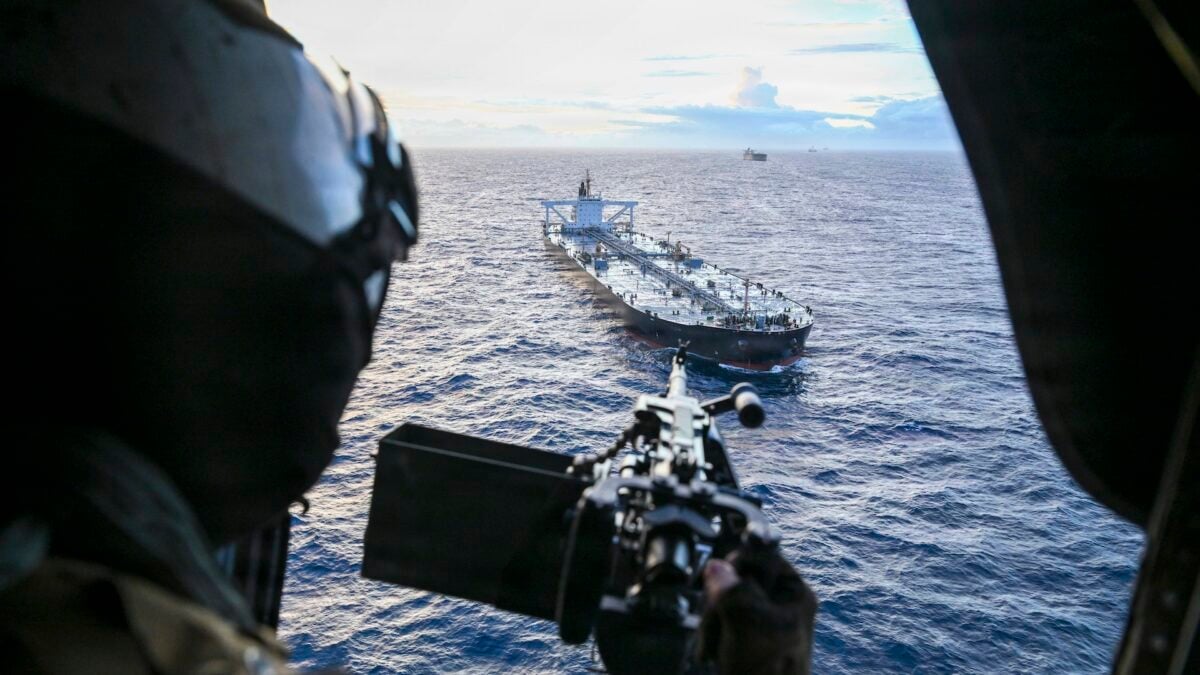
‘Almost Started a War’: US Military Nearly Boarded a Chinese Ship Based on Bad Intel From AI
An AI hallucination nearly triggering a boarding of a Chinese vessel is a live-fire example of why LLMs cannot sit unmediated in command chains. Any operator using AI for threat intel or targeting needs explicit doctrine: where AI can suggest, where humans must verify, and where AI is banned from the loop.
 Applied AI
Nvidia CEO Says There’s ‘0% Chance’ That World Will End in 2030
A major chip CEO publicly assigning “0%” extinction risk to AI is as much a capital signal as a philosophical one — it reassures investors and customers that the buildout will continue. For operators, the takeaway is less about odds and more about planning horizons: assume multi-decade AI infra commitments, with safety debates running in parallel, not as a brake.
 Applied AI
Anthropic is operating a lab that conducts biology experiments
An AI lab running its own wet lab collapses the distance between model capability and real-world bio experimentation—governance, not just safety research, now has to live inside the same org chart as the tools. If you operate in bio or adjacent risk domains, assume leading labs will be direct R&D actors, not just model vendors, and update your dependency and oversight map accordingly.
 Applied AI
AI Hallucination Nearly Triggers US Military Operation
An LLM hallucination getting anywhere near triggering a military operation is the clearest proof yet that AI outputs are already wired into consequential decision loops. If you run systems in defense, critical infrastructure, or finance, you need hard constraints on where model output can flow—not just better prompts or training.